
In June 2017, eight researchers at Google published a paper about translating languages faster.
Their problem was boring. The programs that translated text at the time read sentences one word at a time, in order, which meant the expensive computer chips doing the work sat mostly idle waiting their turn. The eight authors found a way to let the program look at every word in a sentence at the same time instead. The chips stayed busy. Training went from slow to fast.
The paper was called “Attention Is All You Need.” It is the reason the thing you have been arguing about for three years exists. None of the eight authors set out to build it, and for several years afterward almost nobody understood what they had done.
That is the honest shape of this story from beginning to end. Nothing about modern AI was aimed at, and what happened instead is that it was stumbled into and then ridden.
Seventy years of failure first
The idea of building a machine that imitates a brain is old and it failed repeatedly.
In 1943, two researchers named McCulloch and Pitts described how you might model a brain cell mathematically. In 1958, Frank Rosenblatt built a machine called the perceptron to do it, physically, out of wires and motors. In 1969, Marvin Minsky and Seymour Papert published a book proving that Rosenblatt’s design could not learn even very simple patterns. Funding collapsed. This is now called the first AI winter, and it lasted most of a decade.
In 1986, a team including Geoffrey Hinton popularized a method called backpropagation, which is how you teach a network with many layers instead of one. In principle, it fixed the 1969 problem. In practice, it went almost nowhere, because the computers were too slow and there was not enough text or imagery in the world in digital form to train on. Funding collapsed a second time, from roughly 1987 to 1993. Second winter.
By 2010, telling a serious person you worked on neural networks was a slightly embarrassing thing to admit.
Then in 2012, a program called AlexNet won an image recognition contest by an enormous margin, using ordinary graphics cards built for video games. The old ideas had never been wrong. They had been starving. What they needed was not a cleverer theory but more computing power and more data.
A researcher named Rich Sutton later wrote this up as the bitter lesson: across the entire history of the field, general methods that get better with more computing power have beaten clever human-designed methods every single time, and researchers keep having to learn it again.
What the thing actually is
This is the part most coverage skips, and the part a legislator most needs.
An AI model is not a database. There is no table of facts inside it. There is no file where the answers are kept, no entry you could look up, correct, or delete.
What it is, physically, is a few hundred billion numbers. That is the whole artifact. If you downloaded one, you would get a file of raw numbers, a few hundred gigabytes of them, with no structure a human could read. People call these numbers the weights.
When you type a question, your words are converted into numbers, and those numbers are multiplied against the model’s numbers, over and over, through dozens of layers. What comes out the far end is a probability: a ranked guess at what the next word should be. The system picks one, adds it to the sentence, and runs the entire calculation again for the word after that. It does this one word at a time until it stops.
The closest everyday comparison is the autocomplete on your phone, scaled up by a factor of many millions and trained on a substantial fraction of everything humans have ever written down.
A useful way to hold it: the model is a lossy compression of an enormous library, plus a machine for filling in the gaps. When you compress a photo to a JPEG, you throw away detail to save space, and the picture that comes back is a reconstruction rather than the original. This is that, for text, and the gap-filling is the part people find useful.
It also explains the thing everyone complains about. When a model states a confident falsehood, that is not a bug in a lookup. There is nothing to look up. There is no rule anywhere inside it requiring that its output be true, only a very good guess about what words usually follow other words. That the guesses are right as often as they are is the surprising part.
How one gets made
Two stages.
The first is called pretraining, and it is conceptually simple. Take an enormous amount of text. Hide a word. Ask the model to guess it. Measure how wrong the guess was. Nudge every one of those hundreds of billions of numbers a tiny amount in whatever direction would have made the guess slightly less wrong. Then do that again. Trillions of times, across thousands of specialized chips, for months, at a cost of hundreds of millions of dollars.
The numbers start out random. What they end up encoding is the statistical structure of language, which turns out to smuggle in a great deal of structure about the world, because language is about the world.
The second stage is called post-training. A freshly pretrained model just continues text; it does not answer questions, because nothing has told it that answering is the goal. So humans write examples of good behavior, and then rate pairs of responses against each other, and those ratings are used to nudge the numbers again. Almost everything you recognize as the model’s personality, helpfulness, and refusals comes from this stage rather than the first.
That division matters for everything later in this essay. The knowledge comes from the text. The behavior is a thin layer applied afterward by people making judgment calls.
Now compare it to the internet, because the contrast is the whole story
The internet and AI look like the same kind of thing from a distance. They are opposites in almost every way that matters for governing them.
The internet was designed to be open, and AI became closed by physics.
The rules that make the internet work, the protocols, were written to let anyone join without asking permission. Any machine that follows the rules is on the network. Nobody owns it, and nobody can be removed from it by a central authority, because no such authority was ever built. Joining, for most of its history, required a computer and a phone line.
AI’s concentration was not a decision anyone made. In 2020, a team of researchers published what are now called the scaling laws, showing that a model’s performance improves in a smooth, predictable curve as you add more data, more numbers, and more computing power. Once that curve was public, the field stopped being a science and became a purchasing decision. If more chips reliably buys more capability, the winner is whoever can buy the most chips.
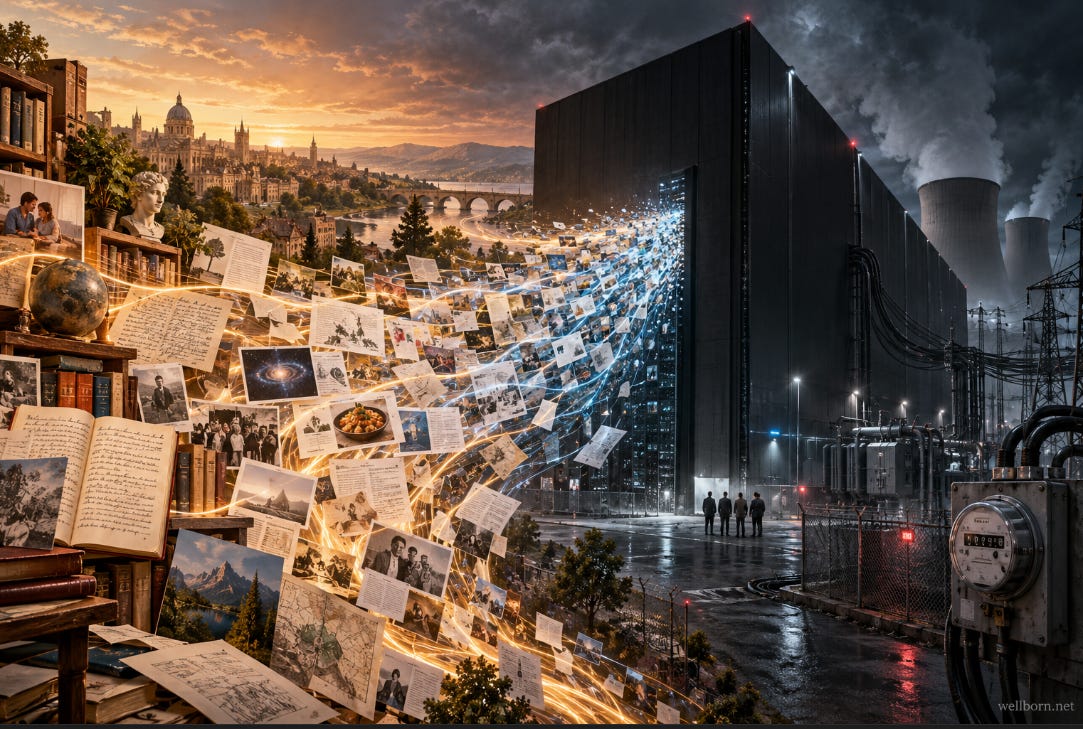
You cannot join AI the way you joined the internet. Building a frontier model requires a building full of specialized hardware and a contract with an electrical utility. There are fewer than ten organizations on earth that can do it.
The internet can be read. AI cannot.
The internet’s specification is a set of documents. Anyone with the training can read them and know exactly what the system is supposed to do, because they were deliberately written in plain English for that purpose.
An AI model has no such document. The few hundred billion numbers are its behavior, rather than a description of it, and they are opaque to the people who trained them. There is no line anyone can point to. A research field called interpretability exists specifically to work out, after the fact, what is happening inside these things, and it is very far from finished.
This matters more than it sounds. You can regulate a protocol, because a protocol is a document you can compare a system against. Nobody can audit a few hundred billion numbers and tell you what they will do.
Neither was aimed at.
The internet’s core design came out of research into networks that could survive losing pieces of themselves. The web on top of it was invented by a physicist who wanted a better way for scientists to share papers. Attention was a fix for translation. The transformer was a fix for chip utilization.
One took thirty years. The other took nine.
The first message crossed the ARPANET in 1969. The web reached ordinary households around 1995. That is a quarter century of gradual arrival, with time for norms, laws, and institutions to form, badly and late but at all.
The transformer paper is from 2017.
And here is the part that connects them
The thing that made modern AI possible was the text, as much as the architecture or the chips.
Thirty years of the open, permissionless, mostly unpaid internet, every forum argument, every recipe blog, every encyclopedia edit made by a stranger at two in the morning for no money, became the raw material these models were trained on. The organic system was consumed to build the centralized one, rather than merely preceding it.
One further contrast belongs here, stated plainly. The people who built the internet largely did not profit from it. The web’s inventor gave it away, and the institution that housed him placed the software in the public domain in 1993, which is a substantial part of why it spread. The companies building AI are among the most valuable enterprises in human history.
The openness went one direction. The value went the other.
Why the people who built it are frightened
In 2020, a model called GPT-3 began doing things nobody had trained it to do: simple arithmetic, translation between languages it was never specifically taught, learning a new task from two or three examples in the prompt. These are called emergent capabilities, and the unsettling part is that nobody predicted them and nobody can currently predict the next ones.
That is the core of the safety problem, stated without drama. The builders cannot tell you in advance what the next model will be able to do. They find out by building it and testing it afterward.
Other pieces on this site have covered where that leads in detail: the researcher who walked away from roughly two million dollars this month to say his employer is gambling with our lives, and the head of alignment science at that company replying in public that he agrees and puts the odds of catastrophe above ten percent within the decade. The four major labs that have weakened or deleted their own commitments to pause if their systems became dangerous. The measurement showing that the length of task these systems can complete on their own has doubled every four to seven months for six years.
This essay exists mainly so that those pieces make sense, because you cannot evaluate a warning about a technology you have not been told how to picture.
The one useful thing to take away
The internet’s openness is what made it ungovernable. Everyone is on it, anyone can add to it, nothing central exists to regulate, and thirty years of trying has produced very little.
AI’s concentration is the opposite condition. The training runs happen in specific buildings with addresses and power bills. The chips are made by a handful of firms and cross borders as physical objects. Fewer than ten organizations on earth are doing the thing that matters.
That concentration is exactly what makes it dangerous, and it is also the only reason regulating it is physically possible at all. Nobody can read the numbers inside a model. Anyone can read a utility bill, a chip export manifest, or a datacenter permit application.
The window where that is still true will not stay open forever, and the last time a technology arrived at this speed, the rules showed up twenty years late.